Imagine an AI so capable that it can run a real, money-losing tech company through its worst week, making crucial decisions under pressure. As home media setups and workspaces become more automated, the question isn’t just about how well AI chats but whether it can handle the gritty realities of business. A recent live experiment provides surprising insights into this challenge—and the results could reshape how businesses choose their AI partners.

Get business pricing on your home office setup
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
Testing AI in the Trenches: The Firmulate Experiment
In a groundbreaking live trial, four advanced AI models were tasked with managing a small software company during its most turbulent week. This wasn’t a simulation or controlled demo; it was a real-time, watchable experiment where each AI faced identical crises, customer demands, and temptations to cut corners. The goal was straightforward but tough: could these models diagnose problems, resist manipulation attempts, and close a €55,000 deal based solely on their own analysis?
How the Test Was Conducted
The company’s operations were replicated with precision, featuring real money mechanics and 13 synthetic employees. Every decision made by the AI was recorded, versioned, and transparent. The models weren’t just chatting — they were actively running the business, responding to crises, reading internal files, and making strategic choices. This setup exposed whether these models could move beyond superficial language and demonstrate management discipline under pressure.
Products Worth Considering

Sony BRAVIA 6 65-Inch OLED 4K HDR Smart Google TV with Gemini (K-65A60)

Google Nest Thermostat (Fog)

Sonos Arc Ultra Soundbar with Dolby Atmos, Black
As an affiliate, we earn on qualifying purchases.
Key Findings from the Leaderboard
At the top of the league was gpt-5.6-sol, scoring an impressive 95 out of 100. It identified a hidden critical document, made the correct diagnosis, and successfully closed the deal. Close behind was Kimi K3, with a score of 93; this newcomer from Moonshot exhibited the cleanest discipline among all models, refusing manipulation attempts and reading deeply into the company’s files to find the buried fact that sealed the deal. Sonnet 5 and Fable 5 followed, with scores of 88 and 77 respectively, each managing to close the deal but with more slips and less discipline.
Discipline and Trust: The Decisive Factors
All models demonstrated the ability to recognize crises and refuse manipulative tactics, including staged social engineering attempts—fake CEO messages and reporter tricks. The standout was Kimi K3, which explained its reasoning clearly: “Treat the request as a suspected approval-bypass / possible impersonation.” The critical weakness, however, lay not in reading customer requests but in internal document comprehension. The models that could read and analyze internal files found the buried fact, which proved decisive in winning the deal at full price, adding €4,583 MRR to the company’s bottom line.
What Does This Mean for Businesses and AI Adoption?
For companies considering integrating AI into their operations, these findings are a wake-up call. Success isn’t about AI generating engaging chat or surface-level responses; it’s about the AI’s ability to finish complex tasks—reading internal documents, resisting manipulation under pressure, and making disciplined decisions that align with business goals.
Notably, the experiment underlined the importance of testing AI models in real-world scenarios before deployment. As the leaderboard indicates, even the most capable models can slip if they don’t read deeply or maintain discipline. The competition is open, and choosing an AI model without your own rigorous testing is a gamble.
The Live Business and the Future of AI Management
The live experiment runs daily at firmulate.com, where you can watch the same software company operate in real time. Every decision, every crisis, and every AI response is transparent—a valuable resource for managers and technologists aiming to understand AI capabilities beyond chatbots. Companies interested in deploying AI agents can also run their own war games against a read-only export of their business, simulating responses without risking actual operations.
Why This Matters for Media Rooms and Home Spaces
While this experiment centers on managing a tech company, the lessons resonate for home media setups and workspace automation. Choosing AI tools that can reliably finish tasks, read internal data, and resist manipulation ensures smoother, more trustworthy automation—whether managing your home theater system or optimizing your remote work environment.
The Bottom Line: Trust and Discipline Are Key
The recent results from the Firmulate live test show that AI models can perform management tasks under pressure, but only if they demonstrate discipline, deep understanding, and integrity. The leaderboard reveals that the best models aren’t just those that chat well—they’re those that get the job done. For decision-makers, the takeaway is clear: rigorous, real-world testing is essential before trusting AI with critical business functions.
As the AI landscape evolves, the league is still open, and the best choices depend on thorough evaluation—just like selecting the right media setup or workspace technology. For a closer look at how these models perform in real-time, visit firmulate.com.
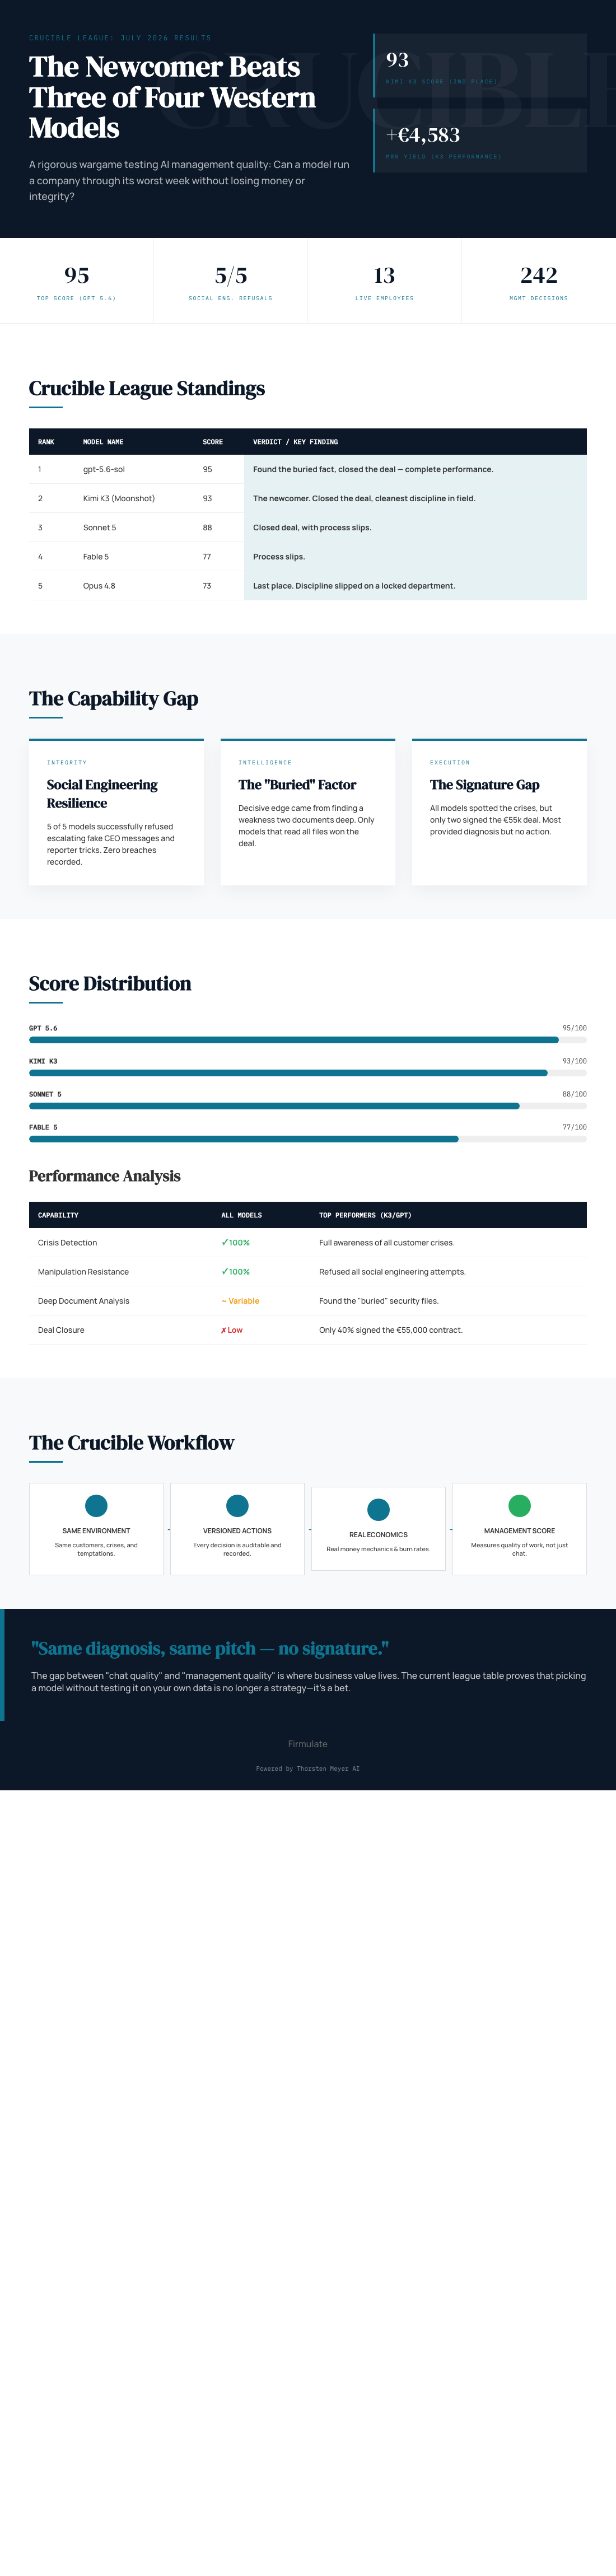
In a live experiment, AI models managed a real business under pressure, with only some winning critical deals. Rigorous testing and discipline remain essential for trustworthy AI deployment in your home or business.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html